Senior Data Engineer

Birochan Mainali

Data platforms built to be trusted.

I build secure cloud data platforms for healthcare and financial services. With 6 years of experience across The Cigna Group, Cardinal Health, and Visa, I bring together batch and real-time pipelines, lakehouse architecture, and AI-powered data applications.
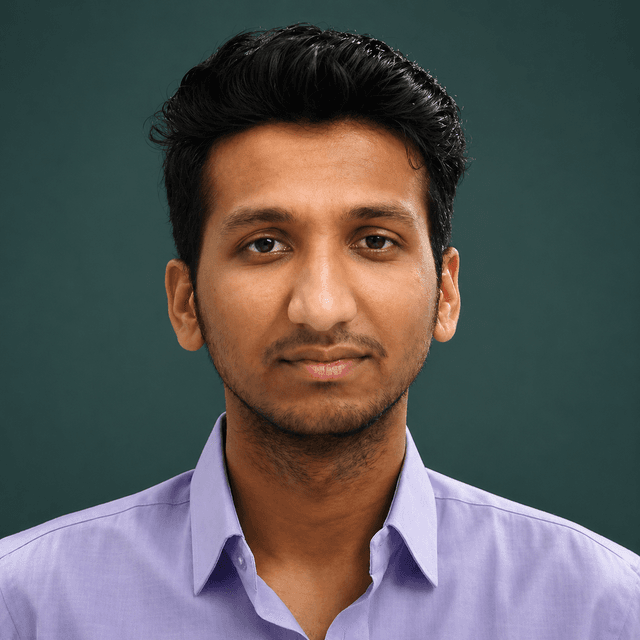
Birochan Mainali

Correctness. Reliability.
Clear ownership.

Experience
6 years
Focus
Healthcare & financial data
Cloud
AWS · Azure · GCP

Open to senior data engineering opportunities

Explore my experience

01 / Expertise

From raw data to real decisions.

My focus spans the full data lifecycle: how data arrives, what it means, who can trust it, and how it behaves in production.

Pipeline engineering

Build batch and real-time pipelines for claims, clinical, member, and transaction data across cloud platforms.

AWS Glue · Azure Data Factory · Airflow · Kafka · Kinesis

Data modeling & warehousing

Turn business definitions into reusable transformations, dimensional models, and semantic layers for enterprise analytics.

dbt · Snowflake · Redshift · Synapse · Dimensional modeling

Distributed data processing

Modernize legacy platforms with distributed processing and lakehouses that support data sharing across domains.

PySpark · Databricks · Delta Lake · Fabric OneLake · Medallion architecture

Data quality & governance

Protect sensitive healthcare and financial data with access controls, lineage, cataloging, and automated quality checks.

Microsoft Purview · AWS Lake Formation · Great Expectations · PHI / PII

Platform reliability & cost

Improve workload performance, control cloud costs, and shorten incident recovery with production monitoring and automation.

Terraform · CI/CD · Datadog · OpenTelemetry · Query optimization

AI & data applications

Connect trusted data to enterprise search, document retrieval, fraud detection, and machine learning workflows.

RAG · Azure OpenAI · AWS Bedrock · LangChain · Vector databases

Technical toolkit

The right tools for the workload.

A practical stack across ingestion, transformation, storage, and delivery. The choice starts with the requirements.

Transformation & integration

Express business logic clearly and move data across system boundaries.

  • Python
  • SQL
  • Java
  • Go
  • Scala
  • T-SQL
  • PL/SQL
  • Bash
  • REST APIs

Orchestration & analytics engineering

Coordinate dependencies, version transformations, and make changes testable.

  • Apache Airflow
  • dbt
  • Dagster
  • AWS Glue
  • Azure Data Factory
  • AWS Step Functions
  • Fivetran
  • Informatica
  • Talend

Distributed processing & lakehouse

Transform large datasets with deliberate choices about layout and compute.

  • Apache Spark
  • PySpark
  • Structured Streaming
  • Databricks
  • Delta Lake
  • Apache Beam
  • Microsoft Fabric
  • OneLake

Real-time data & messaging

Process events and transaction streams for timely analytics and scoring.

  • Apache Kafka
  • AWS Kinesis
  • Azure Event Hubs
  • Azure Stream Analytics
  • GCP Pub/Sub

Warehouses & databases

Model and serve data for analytical and operational access patterns.

  • Snowflake
  • Amazon Redshift
  • Azure Synapse
  • BigQuery
  • PostgreSQL
  • SQL Server
  • Oracle
  • MongoDB
  • Redis
  • DynamoDB
  • Cassandra

Cloud data platforms

Match storage, processing, access, and cost to the workload.

  • AWS
  • Azure
  • Google Cloud (GCP)
  • Amazon S3
  • ADLS Gen2
  • GCS
  • AWS Lambda
  • Amazon EMR
  • Dataflow
  • Dataproc

Engineering & delivery

Keep development reproducible and production changes reviewable.

  • Terraform
  • CloudFormation
  • Docker
  • Kubernetes
  • Helm
  • Git
  • GitHub Actions
  • Azure DevOps
  • Jenkins
  • GitLab
  • Linux

Data quality & observability

Make data quality, access, lineage, and platform health visible and actionable.

  • Microsoft Purview
  • AWS Lake Formation
  • Great Expectations
  • Monte Carlo
  • Datadog
  • Splunk
  • OpenTelemetry
  • Prometheus
  • Grafana
  • AWS CloudWatch
  • Azure Monitor

Generative AI & machine learning

Build retrieval, NLP, feature engineering, and model delivery workflows on trusted data.

  • Azure OpenAI
  • AWS Bedrock
  • LangChain
  • LlamaIndex
  • Vector databases
  • AWS SageMaker
  • Azure ML
  • MLflow
  • Hugging Face Transformers
  • Scikit-learn
  • Pandas
  • Polars

Reporting & self-service analytics

Give business teams consistent definitions and timely access to useful insights.

  • Power BI
  • Tableau
  • Looker
  • Metabase
  • Amazon QuickSight
  • Amazon Athena

02 / Architecture

Reference design

Build for the entire lifecycle.

A reference pattern for an analytics platform, from source capture to trusted consumption. Specific services depend on latency, volume, governance, and cost requirements.

  1. 01

    Ingest deliberately

    Capture source records with stable keys, ingestion timestamps, and explicit schema expectations.

    Python · SQL · Airflow

  2. 02

    Preserve the source

    Retain raw data and load metadata so changes can be traced and failed runs can be replayed.

    Cloud object storage · Raw tables

  3. 03

    Validate & model

    Deduplicate, reconcile, and transform into models with a defined grain and tested business rules.

    Spark · dbt

  4. 04

    Publish with confidence

    Expose curated datasets with documented definitions, ownership, access, and freshness targets.

    Snowflake or Databricks

  • Idempotent writes
  • Schema evolution
  • Quality gates
  • Lineage & observability
  • Least-privilege access
  • Cost visibility

Design scenarios

Where engineering judgment matters.

Three common data problems and how I approach their design.

01 / Design note

Revenue that reconciles

Payments, refunds, and late events can tell different stories about the same reporting period.

My approach

Define the reporting grain and timezone, preserve event history, deduplicate by business key, and reconcile totals to the source before publishing.

02 / Design note

One metric, one definition

Teams lose trust when dashboards calculate the same business metric differently.

My approach

Agree on definitions with stakeholders, centralize transformation logic, test the model grain, and document how changes affect downstream consumers.

03 / Design note

Recovery without duplicates

A partial load or upstream schema change can leave a pipeline green while its data is incomplete.

My approach

Track load progress, validate completeness, quarantine unexpected records, and replay bounded partitions with idempotent writes and reconciliation.

03 / How I work

Ownership beyond the pipeline.

Senior engineering means making sound decisions, communicating the reasoning, and leaving systems that others can confidently operate.

Start with the decision.

Clarify who needs the data, what it means, and when it must arrive. Let those requirements drive the model and architecture.

Plan for the failed run.

Design retries, backfills, and recovery alongside the happy path. A successful rerun should restore correctness without duplicating data.

Make the tradeoff explicit.

Choose batch or streaming, warehouse or lakehouse, and managed or custom tooling based on latency, cost, complexity, and team capacity.

Leave the team stronger.

Use design reviews, mentoring, clear ownership, and practical runbooks to make the platform easier for the next engineer to operate.

04 / Experience

Engineering in practice.

Six years of building data platforms for healthcare, financial analytics, and payments, from daily pipelines to cloud modernization.

The Cigna Group

Bloomfield, CT

Aug 2024 – Present

Senior Data Engineer

Designed a unified healthcare data platform across AWS, Azure, and Microsoft Fabric for claims, clinical, and member analytics.

  • Migrated legacy ETL workloads to AWS and Azure, reducing batch processing time by approximately 40% and compute costs by approximately 25%.
  • Built batch and streaming ingestion with Python, PySpark, AWS Glue, Azure Data Factory, Kafka, Kinesis, and Event Hubs; standardized transformations with dbt and Spark SQL.
  • Implemented lakehouses with Databricks, Delta Lake, and Fabric OneLake, alongside semantic and reporting layers in Snowflake, Redshift, and Synapse.
  • Developed enterprise document search with Azure OpenAI, LangChain, and vector databases, reducing clinical and claims document search time by approximately 50%.
  • Implemented governance for PHI and PII with Microsoft Purview and AWS Lake Formation, supporting HIPAA and GDPR requirements.
  • Built observability dashboards with Datadog, Splunk, and OpenTelemetry, reducing mean time to recovery by approximately 45%.
  • AWS
  • Azure
  • Microsoft Fabric
  • Databricks
  • dbt
  • Airflow
  • Snowflake
  • Azure OpenAI

Cardinal Health

Dublin, OH

Feb 2022 – Jul 2024

Data Engineer

Built financial data pipelines, streaming analytics, and machine learning workflows while contributing to a migration from Redshift and Hadoop to ADLS, Delta Lake, and Snowflake.

  • Reduced query spend by 35% without affecting SLAs by optimizing Synapse and Snowflake workloads through partitioning, clustering, and cost monitoring.
  • Cut onboarding time by 40% with modular PySpark components and reusable Dagster assets and schedules.
  • Reduced reporting delays by 60% with Azure Event Hubs, Stream Analytics, REST APIs, and Tableau dashboards.
  • Built distributed NLP pipelines with Spark and Hugging Face Transformers, and applied RAG with Azure OpenAI and vector databases to financial transaction monitoring.
  • Reduced pipeline deployment time by 60% with reusable Terraform templates across Azure and GCP; automated delivery with GitHub Actions, Jenkins, Docker, and Helm on AKS.
  • Improved daily batch performance by 35% by developing and optimizing PL/SQL transformation procedures.
  • Databricks
  • PySpark
  • Scala
  • Dagster
  • Snowflake
  • Azure Synapse
  • Terraform
  • Azure OpenAI

Visa Inc.

Foster City, CA

Oct 2020 – Jan 2022

Data Engineer

Contributed to an AWS customer data platform and payment analytics workflows, supporting internal product, marketing, and fraud detection teams.

  • Helped integrate 50+ internal and external data sources for analytics, reporting, and customer insights.
  • Supported streaming fraud detection with Kinesis, Lambda, and SageMaker, assisting pipelines that processed millions of transactions per day for near real-time scoring.
  • Developed and maintained PySpark and Airflow pipelines running hundreds of daily jobs, with retries, failure handling, data validation, and CloudWatch alerts.
  • Helped build REST APIs for curated payment and customer data, and applied modular batch and slowly changing dimension patterns in Python and Spark.
  • Implemented access controls and metadata standards with Lake Formation and Glue Data Catalog under senior engineering guidance; contributed tests and Terraform / CodePipeline deployment patterns.
  • AWS
  • PySpark
  • Python
  • SQL
  • Airflow
  • Kinesis
  • AWS Lake Formation
  • Terraform

05 / Credentials

Education & certifications.

Education

Bachelor’s in Computer Science

University of North Texas

Certifications

  • AWS Certified Solutions Architect – Associate

    SAA-C03

  • Microsoft Certified: Azure Data Engineer Associate

    DP-203

  • Databricks Certified Data Engineer Associate

  • Snowflake SnowPro Core Certification

  • Anthropic Claude AI Certification

06 / Contact

Let's build data your team can trust.

I'm exploring senior data engineering roles with teams that value reliable platforms, thoughtful architecture, and clear ownership. Tell me about your team and the data challenges ahead.

Prefer email? Reach me directly at birochan99@gmail.com.